Massimiliano Mancini

Assistant Professor,
University of Trento
Trento, Italy
Hello! I am Massimiliano (Massi) a tenure-track Assistant Professor (RTD-b) at the Department of Information Engineering and Computer Science of University of Trento. The goal of my work is developing algorithms for increasing the generalization capabilities of deep architectures to new visual domains and semantic concepts, focusing on problems such as transfer learning, trustworthiness, and compositionality in computer vision. I am a member of ELLIS.
If you come to Italy, visit my wonderful medieval hometown Monte Santa Maria Tiberina!
news
| Sep 25, 2026 | Three papers accepted at NeurIPS 2026! Topics span data selection for VLM pretraining, text-to-multimodal safety transfer, and compositional image retrieval. Congrats to Matteo, Moreno, and Yuanmin! |
|---|---|
| Aug 28, 2026 | I will give a talk at VISMAC 2026 regarding machine unlearning. If you are a Ph.D. student on computer vision, consider attending this amazing school! |
| Jul 03, 2026 | We got 2 papers accepted at ECCV 2026! 😁 Congrats to Thomas (benchmarking proactiveness in multimodal LLMs) and Deepayan (personalizing MLLMs via a reinforced reference game)! |
selected publications
-
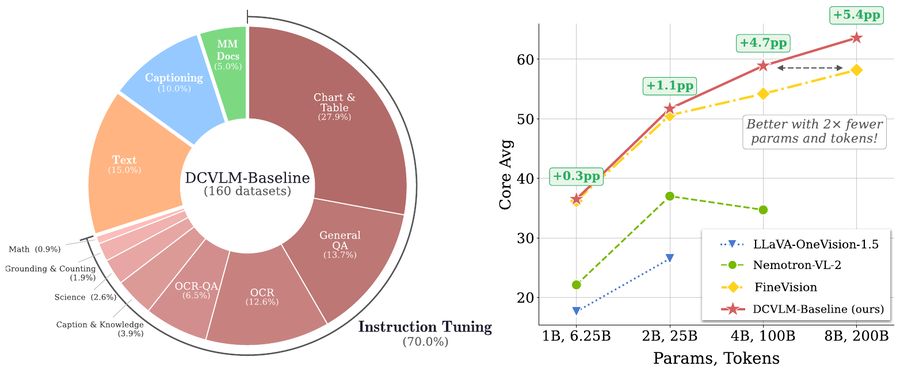 DataComp-VLM: Improved Open Datasets for Vision-Language ModelsMatteo Farina , Vishaal Udandarao , Thao Nguyen , and 33 more authorsAdvances in Neural Information Processing Systems (NeurIPS), 2026
Building performant Vision-Language Models (VLMs) requires carefully curating large-scale training datasets, yet the community lacks systematic benchmarks for evaluating such curation strategies. We introduce DataComp for VLMs (DCVLM), a benchmark for controlled data-centric experiments to improve VLM training. As part of DCVLM, we collect 160 datasets spanning four data types—image-caption pairs, multimodal interleaved documents, text-only, and instruction-tuning data—into a corpus of 6T multimodal tokens. DCVLM allows participants to test curation strategies (filtering, mixing, formatting, sampling) across 1B–8B models and 6.25B–200B token budgets. Models are then evaluated on a carefully selected suite of up to 52 downstream benchmarks across 9 domains. We conduct extensive experiments on DCVLM and find that data mixing, not filtering, is key to a high-quality training dataset: instruction-heavy mixtures scale better than caption-heavy ones, with gains widening at larger scales. The resulting dataset, DCVLM-Baseline, enables training an 8B VLM to 63.6% accuracy on our 33-task core suite with 200B training tokens. Compared to FineVision, the state-of-the-art open VLM training dataset, this represents an improvement of +5.4pp. DCVLM and all accompanying artifacts will be made publicly available.
@article{farina2026dcvlm, title = {DataComp-VLM: Improved Open Datasets for Vision-Language Models}, author = {Farina, Matteo and Udandarao, Vishaal and Nguyen, Thao and Kuzucu, Selim and Böther, Maximilian and Hochlehnert, Andreas and Ghosh, Adhiraj and Nezhurina, Marianna and Roth, Karsten and Struber, Joschka and Zhang, Yuhui and Dziadzio, Sebastian and Sui, Elaine and Jahagirdar, Soumya and Ghosh, Dhruba and Hammoud, Hasan and De Min, Thomas and Caldarella, Simone and Mirza, Jehanzeb and Keh, Sedrick and Cherti, Mehdi and Kuehne, Hilde and Schiele, Bernt and Yeung-Levy, Serena and Naeem, Muhammad Ferjad and Tombari, Federico and Klimovic, Ana and Ricci, Elisa and Bethge, Matthias and Oh, Sewoong and Prabhu, Ameya and Tonioni, Alessio and Jitsev, Jenia and Mancini, Massimiliano and Schmidt, Ludwig and Parthasarathy, Nikhil}, journal = {Advances in Neural Information Processing Systems (NeurIPS)}, year = {2026}, } -
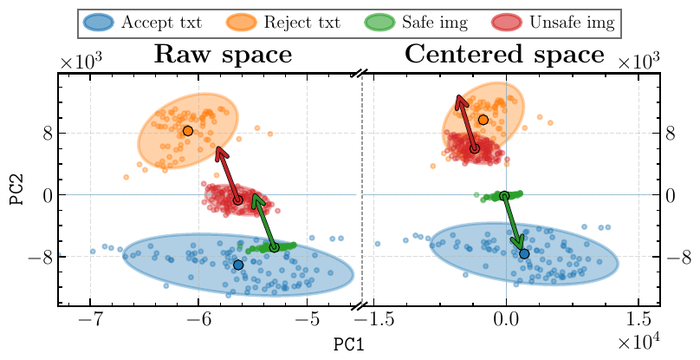 Harnessing Textual Refusal Directions for Multimodal SafetyMoreno D’Incà , Nicu Sebe , and Massimiliano ManciniAdvances in Neural Information Processing Systems (NeurIPS), 2026
To improve safety in Large Language Models (LLMs) we can either perform post-training alignment or exploit refusal directions in the activation space. Both strategies are less feasible in Multimodal LLMs (MLLMs) as they require unsafe multimodal data, harder to collect than their unimodal counterpart. In this work, we relax this constraint and investigate whether textual refusal directions, extracted directly from the LLM backbone, generalize across modalities (i.e., image, video). Preliminary findings confirm this ability, though effectiveness is conditioned by layer selection, steering strength, and cross-modal alignment, with the latter causing safe multimodal inputs to be spuriously steered toward refusal. Building on this, we introduce Modality-Agnostic Refusal Steering (MARS), a light-weight training-free approach that injects multimodal safety without the need for multimodal safety data. MARS corrects modality misalignment via activation re-centering, adaptively scales steering strength within a geometrically defined trust region, and selects the optimal intervention layer, operating at the first generated token. Evaluated on five SOTA MLLMs across safety, utility, and video jailbreak benchmarks, MARS achieves consistent safety gains while preserving utility. These results reveal that safety-relevant structure is shared across modalities and that textual refusal directions are a powerful and underexplored foundation for multimodal alignment.
@article{dinca2026mars, title = {Harnessing Textual Refusal Directions for Multimodal Safety}, author = {D'Incà, Moreno and Sebe, Nicu and Mancini, Massimiliano}, journal = {Advances in Neural Information Processing Systems (NeurIPS)}, year = {2026}, } -
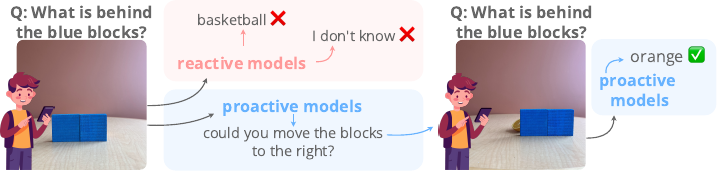 ProactiveBench: Benchmarking Proactiveness in Multimodal Large Language ModelsThomas De Min , Subhankar Roy , Stéphane Lathuilière , and 2 more authorsIn European Conference on Computer Vision (ECCV) , 2026
Effective collaboration begins with knowing when to ask for help. For example, when trying to identify an occluded object, a human would ask someone to remove the obstruction. Can MLLMs exhibit a similar "proactive" behavior by requesting simple user interventions? To investigate this, we introduce ProactiveBench, a benchmark built from seven repurposed datasets that tests proactiveness across different tasks such as recognizing occluded objects, enhancing image quality, and interpreting coarse sketches. We evaluate 22 MLLMs on ProactiveBench, showing that (i) they generally lack proactiveness; (ii) proactiveness does not correlate with model capacity; (iii) hinting at proactiveness yields only marginal gains. Surprisingly, we found that conversation histories and in-context learning introduce negative biases, hindering performance. Finally, we explore a simple fine-tuning strategy based on reinforcement learning: its results suggest that proactiveness can be learned, even generalizing to unseen scenarios. We publicly release ProactiveBench as a first step toward building proactive multimodal models.
@inproceedings{demin2026proactivebench, title = {ProactiveBench: Benchmarking Proactiveness in Multimodal Large Language Models}, author = {De Min, Thomas and Roy, Subhankar and Lathuilière, Stéphane and Ricci, Elisa and Mancini, Massimiliano}, booktitle = {European Conference on Computer Vision (ECCV)}, year = {2026}, } -
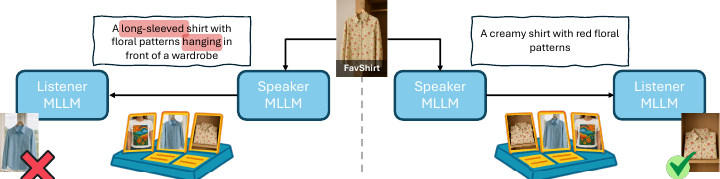 Personalizing MLLMs via Reinforced Multimodal Reference GameDeepayan Das , Davide Talon , Yiming Wang , and 2 more authorsIn European Conference on Computer Vision (ECCV) , 2026
Personalizing Multimodal Large Language Models (MLLMs) aims to recognize users’ unique concepts from visual data and provide personalized responses. Although prior work has shown the benefit of concept descriptions and reasoning for this task, MLLM descriptions often include information, such as state and context, that does not help and may in fact hinder the unique identification of the target concept among other visually similar items. Effective descriptions of personal concepts should instead be accurate, discriminative, and free of distracting details. To achieve such descriptions, we introduce Reinforced Reference Game (RRG), a learning framework that promotes discriminative descriptions through a novel reinforced multimodal reference game. The MLLM plays both the roles of speaker and listener in a contrastive game setting, whose goal is to effectively communicate discriminative information about a target concept. Our approach formulates a verifiable contrastive reward over hard positives (dissimilar views of the same concept) and hard negatives (visually similar but different concepts). Empirically, RRG achieves state-of-the-art across multiple tasks on three personalization benchmarks. RRG generalizes to unseen domains and outperforms existing methods based on concept descriptions and personalization-specific RL frameworks.
@inproceedings{das2026rrg, title = {Personalizing MLLMs via Reinforced Multimodal Reference Game}, author = {Das, Deepayan and Talon, Davide and Wang, Yiming and Mancini, Massimiliano and Ricci, Elisa}, booktitle = {European Conference on Computer Vision (ECCV)}, year = {2026}, } -
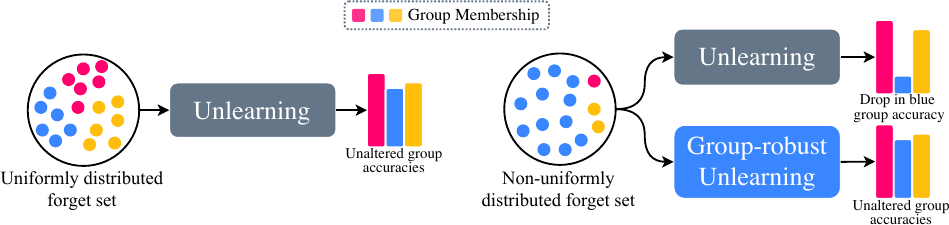 Group-robust Machine UnlearningThomas De Min , Subhankar Roy , Stéphane Lathuilière , and 2 more authorsIn Transactions on Machine Learning Research , 2025
Machine unlearning is an emerging paradigm to remove the influence of specific training data (i.e., the forget set) from a model while preserving its knowledge of the rest of the data (i.e., the retain set). Previous approaches assume the forget data to be uniformly distributed from all training datapoints. However, if the data to unlearn is dominant in one group (e.g., ethnicity, gender), we empirically show that performance for this group degrades, leading to fairness issues. To perform unlearning while preserving fairness, this work addresses the overlooked problem of non-uniformly distributed forget sets, which we refer to as group-robust machine unlearning. We formalize the problem and present a simple and effective exact unlearning strategy that mitigates the performance loss in dominant groups via sample distribution reweighting. Moreover, we present MIU (Mutual Information-aware Machine Unlearning), the first approach for group robustness in approximate machine unlearning. MIU minimizes the mutual information between model features and group information, achieving unlearning while reducing performance degradation in the dominant group of the forget set. Additionally, MIU exploits sample distribution reweighting and mutual information calibration with the original model to preserve group robustness. We conduct experiments on three datasets and show that MIU outperforms standard methods, achieving unlearning without compromising model robustness.
@inproceedings{demin2025group, title = {Group-robust Machine Unlearning}, author = {De Min, Thomas and Roy, Subhankar and Lathuilière, Stéphane and Ricci, Elisa and Mancini, Massimiliano}, booktitle = {Transactions on Machine Learning Research}, year = {2025}, } -
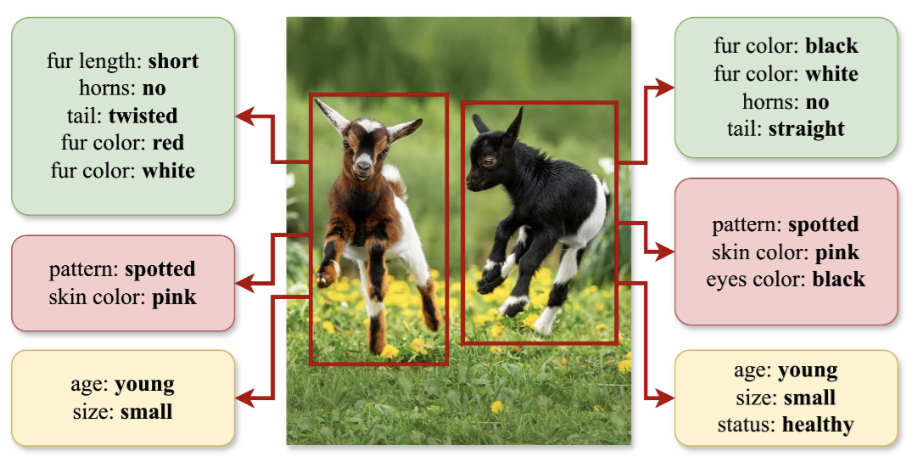 Compositional Caching for Training-free Open-vocabulary Attribute DetectionMarco Garosi , Alessandro Conti , Gaowen Liu , and 2 more authorsIn , 2025(Highlight)
Attribute detection is crucial for many computer vision tasks, as it enables systems to describe properties such as color, texture, and material. Current approaches often rely on labor-intensive annotation processes which are inherently limited: objects can be described at an arbitrary level of detail (eg, color vs. color shades), leading to ambiguities when the annotators are not instructed carefully. Furthermore, they operate within a predefined set of attributes, reducing scalability and adaptability to unforeseen downstream applications. We present Compositional Caching (ComCa), a training-free method for open-vocabulary attribute detection that overcomes these constraints. ComCa requires only the list of target attributes and objects as input, using them to populate an auxiliary cache of images by leveraging web-scale databases and Large Language Models to determine attribute-object compatibility. To account for the compositional nature of attributes, cache images receive soft attribute labels. Those are aggregated at inference time based on the similarity between the input and cache images, refining the predictions of underlying Vision-Language Models (VLMs). Importantly, our approach is model-agnostic, compatible with various VLMs. Experiments on public datasets demonstrate that ComCa significantly outperforms zero-shot and cache-based baselines, competing with recent training-based methods, proving that a carefully designed training-free approach can successfully address open-vocabulary attribute detection.
@inproceedings{garosi2025comca, title = {Compositional Caching for Training-free Open-vocabulary Attribute Detection}, author = {Garosi, Marco and Conti, Alessandro and Liu, Gaowen and Ricci, Elisa and Mancini, Massimiliano}, journal = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition}, year = {2025}, note = {(Highlight)}, } -
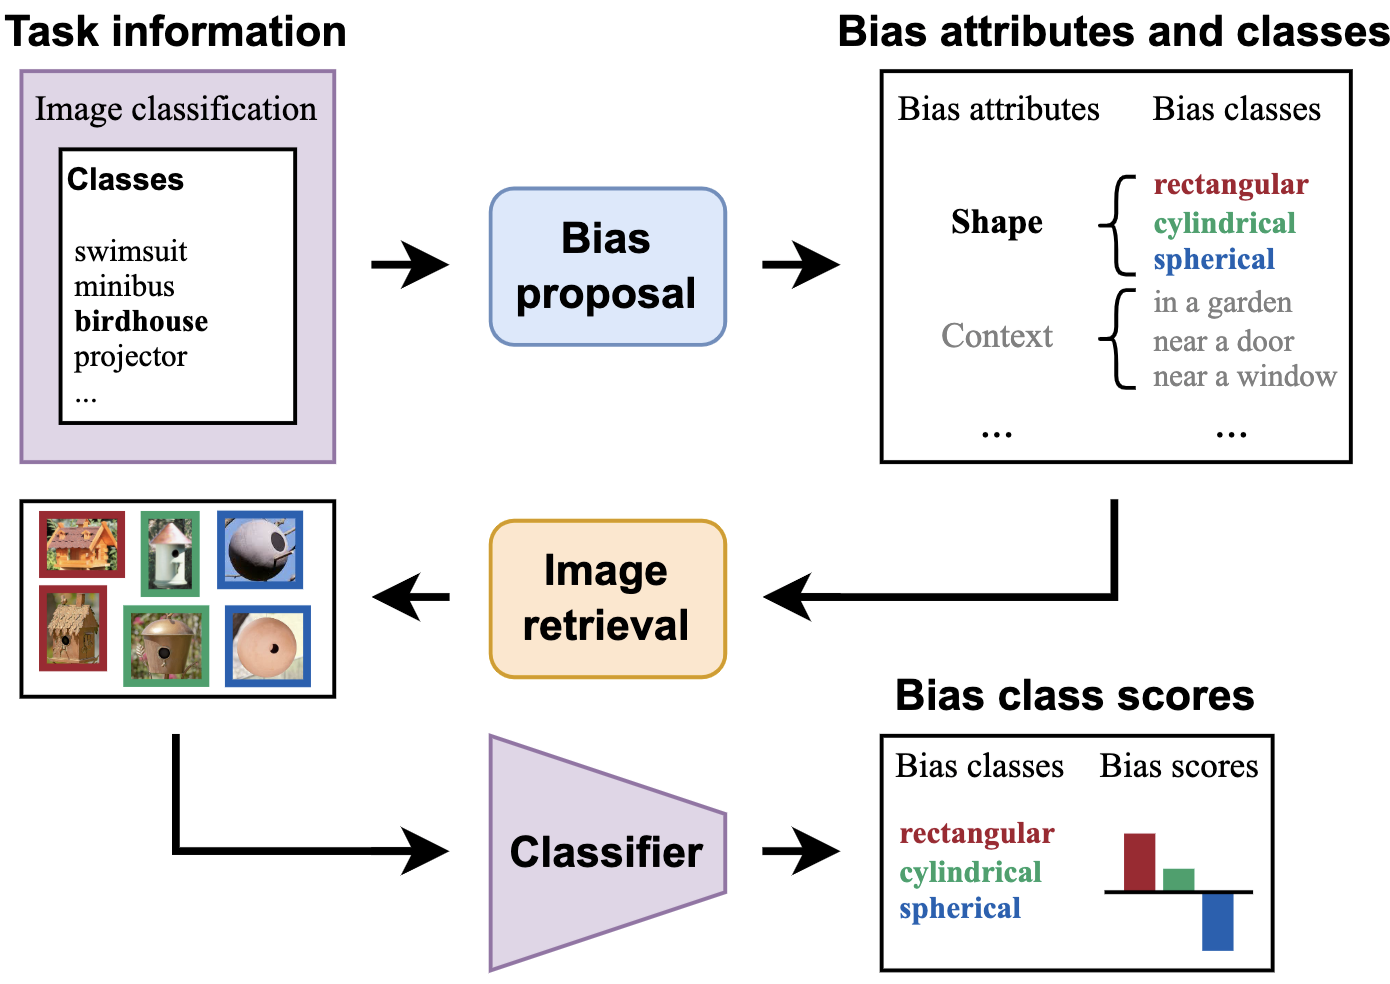 Classifier-to-Bias: Toward Unsupervised Automatic Bias Detection for Visual ClassifiersQuentin Guimard , Moreno D’Incà , Elia Peruzzo , and 2 more authorsProceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2025
A person downloading a pre-trained model from the web should be aware of its biases. Existing approaches for bias identification rely on datasets containing labels for the task of interest, something that a non-expert may not have access to, or may not have the necessary resources to collect: this greatly limits the number of tasks where model biases can be identified. In this work, we present Classifier-to-Bias (C2B), the first bias discovery framework that works without access to any labeled data: it only relies on a textual description of the classification task to identify biases in the target classification model. This description is fed to a large language model to generate bias proposals and corresponding captions depicting biases together with task-specific target labels. A retrieval model collects images for those captions, which are then used to assess the accuracy of the model wrt the given biases. C2B is training-free, does not require any annotations, has no constraints on the list of biases, and can be applied to any pre-trained model on any classification task. Experiments on two publicly available datasets show that C2B discovers biases beyond those of the original datasets and outperforms a recent state-of-the-art bias detection baseline that relies on task-specific annotations, being a promising first step toward addressing task-agnostic unsupervised bias detection.
@article{guimard2025c2b, title = {Classifier-to-Bias: Toward Unsupervised Automatic Bias Detection for Visual Classifiers}, author = {Guimard, Quentin and D'Incà, Moreno and Peruzzo, Elia and Mancini, Massimiliano and Ricci, Elisa}, journal = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition}, year = {2025}, } -
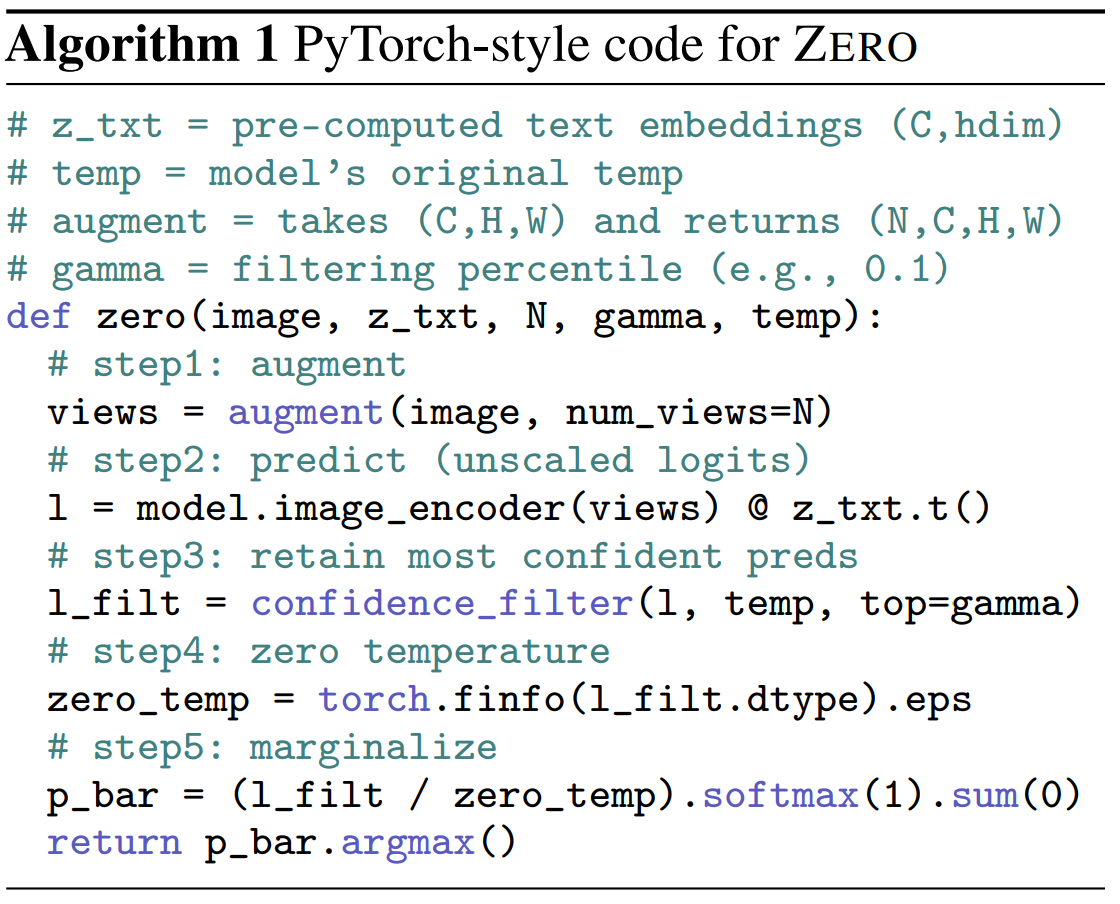 Frustratingly Easy Test-Time Adaptation of Vision-Language ModelsMatteo Farina , Gianni Franchi , Giovanni Iacca , and 2 more authorsAdvances in Neural Information Processing Systems (NeurIPS), Dec 2024
Vision-Language Models seamlessly discriminate among arbitrary semantic categories, yet they still suffer from poor generalization when presented with challenging examples. For this reason, Episodic Test-Time Adaptation (TTA) strategies have recently emerged as powerful techniques to adapt VLMs in the presence of a single unlabeled image. The recent literature on TTA is dominated by the paradigm of prompt tuning by Marginal Entropy Minimization, which, relying on online backpropagation, inevitably slows down inference while increasing memory. In this work, we theoretically investigate the properties of this approach and unveil that a surprisingly strong TTA method lies dormant and hidden within it. We term this approach ZERO (TTA with “zero” temperature), whose design is both incredibly effective and frustratingly simple: augment N times, predict, retain the most confident predictions, and marginalize after setting the Softmax temperature to zero. Remarkably, ZERO requires a single batched forward pass through the vision encoder only and no backward passes. We thoroughly evaluate our approach following the experimental protocol established in the literature and show that ZERO largely surpasses or compares favorably w.r.t. the state-of-the-art while being almost 10× faster and 13× more memory friendly than standard Test-Time Prompt Tuning. Thanks to its simplicity and comparatively negligible computation, ZERO can serve as a strong baseline for future work in this field. Code will be available.
@article{farina2024frustratingly, title = {Frustratingly Easy Test-Time Adaptation of Vision-Language Models}, author = {Farina, Matteo and Franchi, Gianni and Iacca, Giovanni and Mancini, Massimiliano and Ricci, Elisa}, journal = {Advances in Neural Information Processing Systems (NeurIPS)}, year = {2024}, month = dec, } -
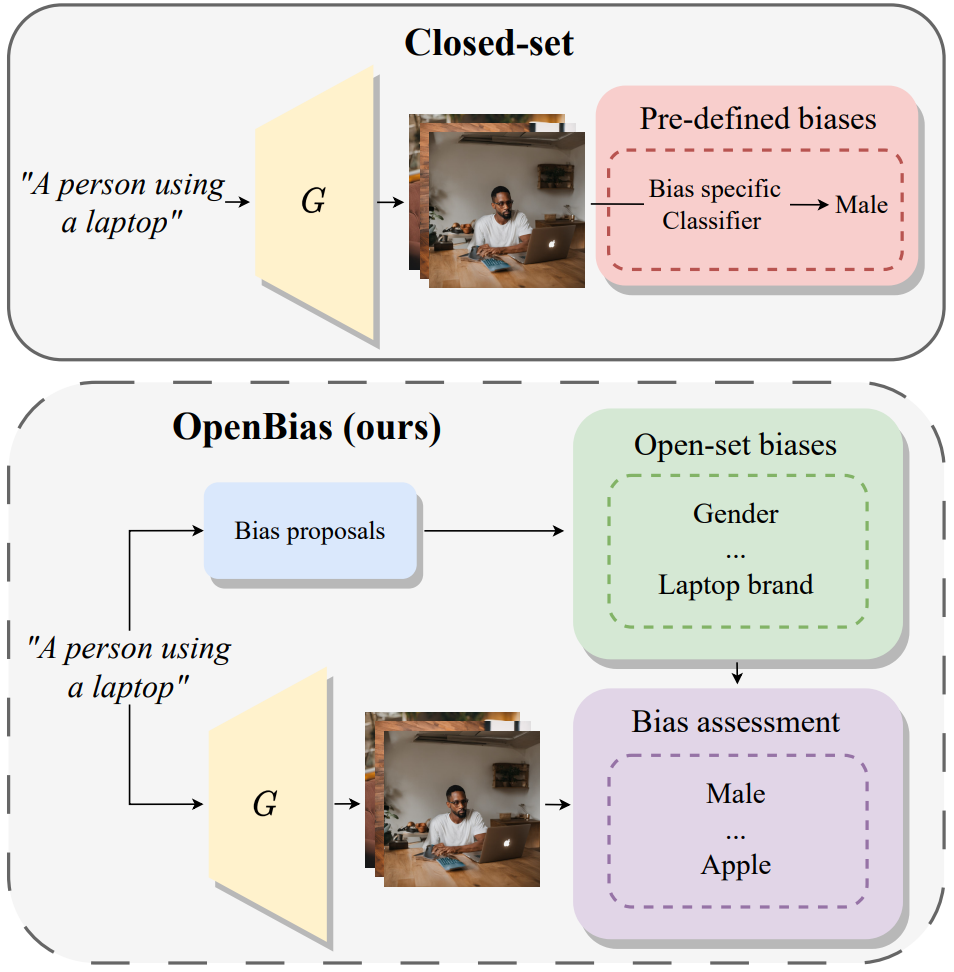 OpenBias: Open-set Bias Detection in Text-to-Image Generative ModelsMoreno D’Incà , Elia Peruzzo , Massimiliano Mancini, and 6 more authorsIEEE/CVF Conference on Computer Vision and Pattern Recognition, Dec 2024(Highlight)
Text-to-image generative models are becoming increasingly popular and accessible to the general public. As these models see large-scale deployments it is necessary to deeply investigate their safety and fairness to not disseminate and perpetuate any kind of biases. However existing works focus on detecting closed sets of biases defined a priori limiting the studies to well-known concepts. In this paper we tackle the challenge of open-set bias detection in text-to-image generative models presenting OpenBias a new pipeline that identifies and quantifies the severity of biases agnostically without access to any precompiled set. OpenBias has three stages. In the first phase we leverage a Large Language Model (LLM) to propose biases given a set of captions. Secondly the target generative model produces images using the same set of captions. Lastly a Vision Question Answering model recognizes the presence and extent of the previously proposed biases. We study the behavior of Stable Diffusion 1.5 2 and XL emphasizing new biases never investigated before. Via quantitative experiments we demonstrate that OpenBias agrees with current closed-set bias detection methods and human judgement.
@article{dinca2024openbias, title = {OpenBias: Open-set Bias Detection in Text-to-Image Generative Models}, author = {D'Incà, Moreno and Peruzzo, Elia and Mancini, Massimiliano and Xu, Dejia and Goel, Vidit and Xu, Xingqian and Wang, Zhangyang and Shi, Humphrey and Sebe, Nicu}, journal = {IEEE/CVF Conference on Computer Vision and Pattern Recognition}, year = {2024}, note = {(Highlight)}, } -
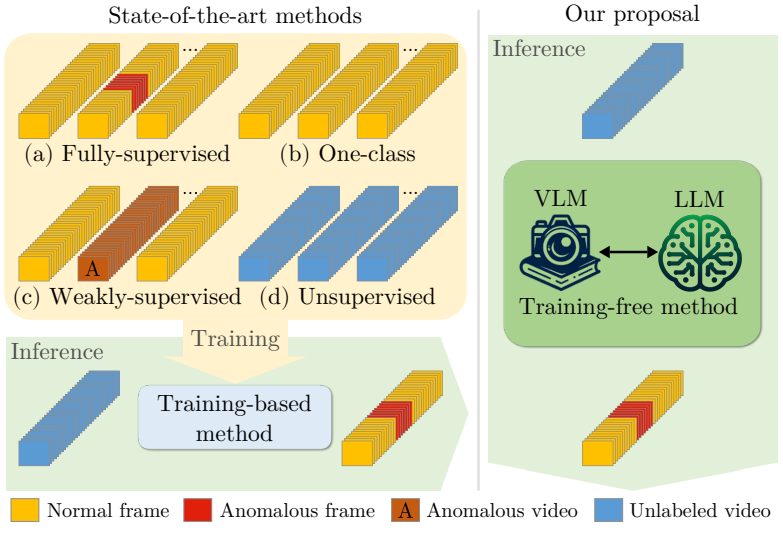 Harnessing Large Language Models for Training-free Video Anomaly DetectionLuca Zanella , Willi Menapace , Massimiliano Mancini, and 2 more authorsIEEE/CVF Conference on Computer Vision and Pattern Recognition, Dec 2024
Video anomaly detection (VAD) aims to temporally locate abnormal events in a video. Existing works mostly rely on training deep models to learn the distribution of normality with either video-level supervision one-class supervision or in an unsupervised setting. Training-based methods are prone to be domain-specific thus being costly for practical deployment as any domain change will involve data collection and model training. In this paper we radically depart from previous efforts and propose LAnguage-based VAD (LAVAD) a method tackling VAD in a novel training-free paradigm exploiting the capabilities of pre-trained large language models (LLMs) and existing vision-language models (VLMs). We leverage VLM-based captioning models to generate textual descriptions for each frame of any test video. With the textual scene description we then devise a prompting mechanism to unlock the capability of LLMs in terms of temporal aggregation and anomaly score estimation turning LLMs into an effective video anomaly detector. We further leverage modality-aligned VLMs and propose effective techniques based on cross-modal similarity for cleaning noisy captions and refining the LLM-based anomaly scores. We evaluate LAVAD on two large datasets featuring real-world surveillance scenarios (UCF-Crime and XD-Violence) showing that it outperforms both unsupervised and one-class methods without requiring any training or data collection.
@article{zanella2024lavad, title = {Harnessing Large Language Models for Training-free Video Anomaly Detection}, author = {Zanella, Luca and Menapace, Willi and Mancini, Massimiliano and Wang, Yiming and Ricci, Elisa}, journal = {IEEE/CVF Conference on Computer Vision and Pattern Recognition}, year = {2024}, } -
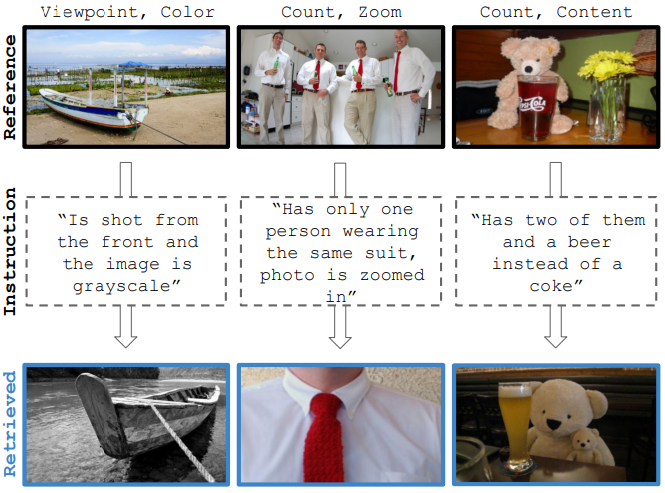 Vision-by-Language for Training-Free Compositional Image RetrievalShyamgopal Karthik , Karsten Roth , Massimiliano Mancini, and 1 more authorIn International Conference on Learning Representations (ICLR) , Dec 2024
Given an image and a target modification (e.g an image of the Eiffel tower and the text “without people and at night-time”), Compositional Image Retrieval (CIR) aims to retrieve the relevant target image in a database. While supervised approaches rely on annotating triplets that is costly (i.e. query image, textual modification, and target image), recent research sidesteps this need by using large-scale vision-language models (VLMs), performing Zero-Shot CIR (ZS-CIR). However, state-of-the-art approaches in ZS-CIR still require training task-specific, customized models over large amounts of image-text pairs. In this work, we proposeto tackle CIR in a training-free manner via our Compositional Image Retrieval through Vision-by-Language (CIReVL), a simple, yet human-understandable and scalable pipeline that effectively recombines large-scale VLMs with large language models (LLMs). By captioning the reference image using a pre-trained generative VLM and asking a LLM to recompose the caption based on the textual target modification for subsequent retrieval via e.g. CLIP, we achieve modular language reasoning. In four ZS-CIR benchmarks, we find competitive, in-part state-of-the-art performance - improving over supervised methods Moreover, the modularity of CIReVL offers simple scalability without re-training, allowing us to both investigate scaling laws and bottlenecks for ZS-CIR while easily scaling up to in parts more than double of previously reported results. Finally, we show that CIReVL makes CIR human-understandable by composing image and text in a modular fashion in the language domain, thereby making it intervenable, allowing to post-hoc re-align failure cases. Code will be released upon acceptance.
@inproceedings{Karthik_2024_ICLR, author = {Karthik, Shyamgopal and Roth, Karsten and Mancini, Massimiliano and Akata, Zeynep}, title = {Vision-by-Language for Training-Free Compositional Image Retrieval}, booktitle = {International Conference on Learning Representations (ICLR)}, year = {2024}, } -
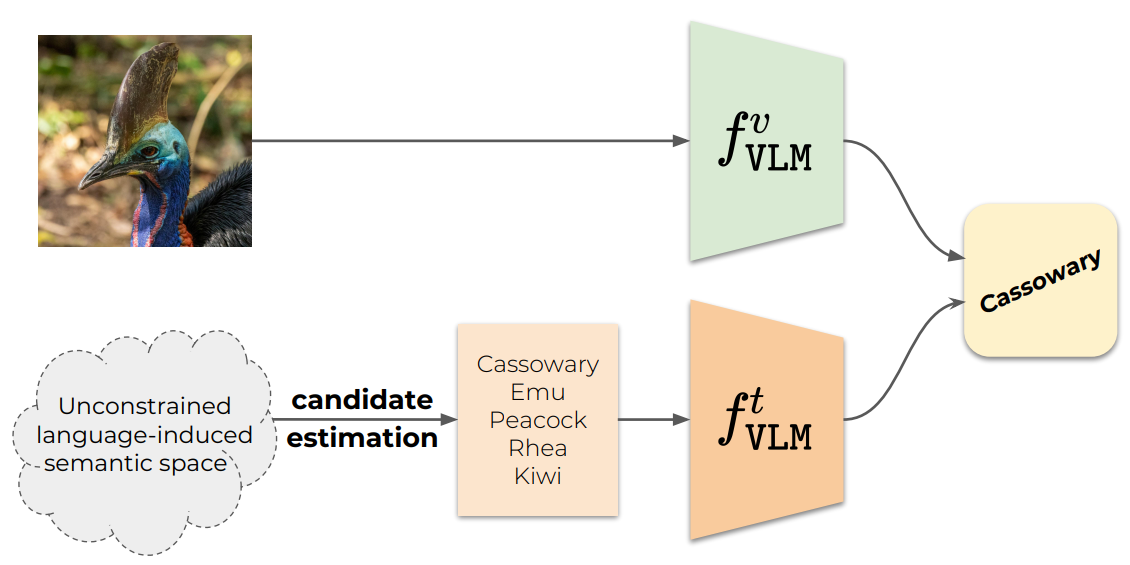 Vocabulary-free Image ClassificationAlessandro Conti , Enrico Fini , Massimiliano Mancini, and 3 more authorsAdvances in Neural Information Processing Systems (NeurIPS), Dec 2023
Recent advances in large vision-language models have revolutionized the image classification paradigm. Despite showing impressive zero-shot capabilities, a pre-defined set of categories, a.k.a. the vocabulary, is assumed at test time for composing the textual prompts. However, such assumption can be impractical when the semantic context is unknown and evolving. We thus formalize a novel task, termed as Vocabulary-free Image Classification (VIC), where we aim to assign to an input image a class that resides in an unconstrained language-induced semantic space, without the prerequisite of a known vocabulary. VIC is a challenging task as the semantic space is extremely large, containing millions of concepts, with hard-to-discriminate fine-grained categories.
@article{conti2023vocabulary,
  title = {Vocabulary-free Image Classification},
  author = {Conti, Alessandro and Fini, Enrico and Mancini, Massimiliano and Rota, Paolo and Wang, Yiming and Ricci, Elisa},
  journal = {Advances in Neural Information Processing Systems (NeurIPS)},
  year = {2023},
}


